On March 26, 2026, OpenAI shut down access to gpt-4-0314, the snapshot that shipped with the original GPT-4. OpenAI's deprecations page lists its price as $30.00 per million input tokens and $60.00 per million output tokens. The March 2023 launch post priced gpt-4 at $0.03 per 1K prompt tokens and $0.06 per 1K completion tokens. GPT-4's pricing history follows a pattern. The big price drops came as new model names. The old snapshot kept its launch price until it was switched off.
GPT-4 launch price vs current price, model by model
GPT-4 was announced on March 14, 2023. It had a context length of 8,192 tokens and default rate limits of 40k tokens per minute. A long-context version, gpt-4-32k, cost $0.06 per 1K prompt tokens and $0.12 per 1K completion tokens, or $60 and $120 per million. OpenAI made GPT-4 generally available to all developers in July.
GPT-4 Turbo came out of DevDay, which OpenAI's deprecations page dates to November 6, 2023. OpenAI priced it at a 3x cheaper rate for input tokens and 2x cheaper for output compared with GPT-4, with a 128k context window. In dollars, that's $10 input, $30 output per million tokens.
GPT-4.1 launched on April 14, 2025, at $2.00 input, $0.50 cached input and $8.00 output. OpenAI compared it to GPT-4o and called it 26% less expensive for median queries.
| Model | Launch date | Input / 1M | Output / 1M | Source |
|---|---|---|---|---|
| GPT-4 (8K) | Mar 2023 | $30.00 | $60.00 | OpenAI GPT-4 post |
| GPT-4 Turbo | Nov 2023 | $10.00 | $30.00 | OpenAI GPT-4 Turbo docs |
| GPT-4.1 | Apr 2025 | $2.00 | $8.00 | OpenAI GPT-4.1 post |
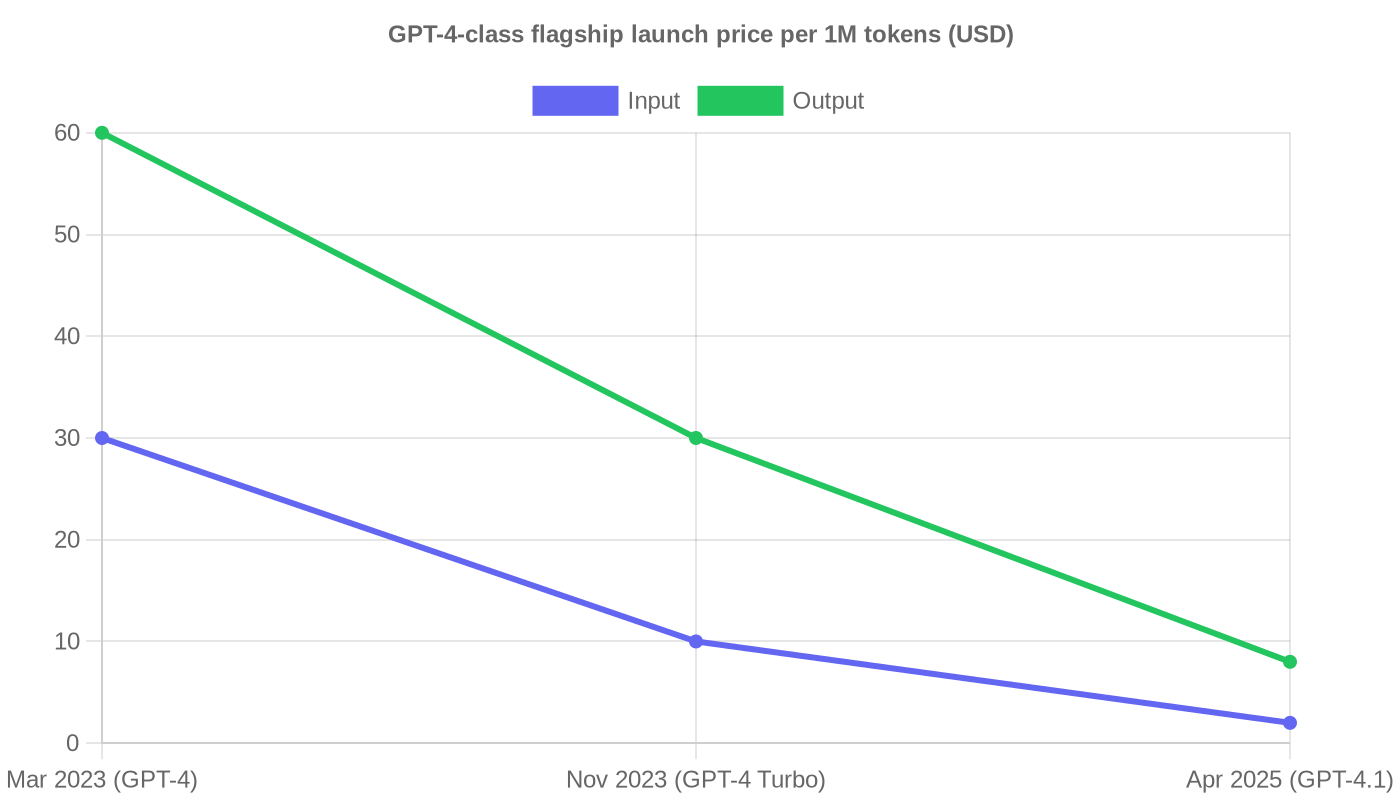 GPT-4-class flagship launch price per 1M tokens (USD)
What OpenAI says drove the cuts
OpenAI gave nearly the same reason both times. For GPT-4 Turbo, it said it had "optimized its performance" so it could charge less. For GPT-4.1, it pointed to "efficiency improvements to our inference systems". The models weren't sold at a loss. Each one cost less to run than the one before.
A second force is less obvious: the expensive, experimental tier keeps getting cut. GPT-4.5 was introduced as a research preview of a large, compute-intensive model. OpenAI began deprecating it because GPT-4.1 offers improved or similar performance on many key capabilities at much lower cost and latency. The preview was turned off on July 14, 2025.
The long-context surcharge went away too, and that's the underrated change. In 2023, going from 8K to 32K context doubled the per-token price, from $0.03/$0.06 to $0.06/$0.12 per 1K tokens. GPT-4.1 supports up to 1 million tokens of context and charges no additional cost beyond the standard per-token costs for long requests. OpenAI also raised the prompt caching discount to 75%, up from 50%, and it trained GPT-4.1 to follow diff formats more reliably. That way the model outputs only the changed lines, not the whole file. Since output is the most expensive token you buy, that saves real money.
You only get the cut if you switch models
| Date | Event | Impact |
|---|---|---|
| Jul 2023 | GPT-4 generally available | Open to all developers |
| Nov 6, 2023 | DevDay: GPT-4 Turbo | 3x cheaper input, 128k context |
| Jul 14, 2025 | GPT-4.5 Preview turned off | Expensive preview retired |
| Mar 26, 2026 | Legacy snapshots shut down | Forced migration off 0314 |
Every price drop in this timeline required you to make a move. No existing model got a discount. The March 2026 shutdown hit both gpt-4-0314 and gpt-4-0125-preview, including the gpt-4-turbo-preview alias. OpenAI recommends gpt-5 or gpt-4.1 as replacements for gpt-4-0314.
Teams still on GPT-4 Turbo pay $10.00 per million input tokens and $30.00 per million output tokens. GPT-4.1 lists $2.00 input and $8.00 output, so switching cuts input cost by 80% and output cost by about 73%. Check which model string your code sends today.
Budgeting an AI feature in late 2026
Start with the model string. Across the GPT-4 family, prices run as high as $10.00 input, $30.00 output per million tokens for GPT-4 Turbo. Picking the wrong model costs you far more than any tweak you make later.
Next, plan for context to pile up. Multiply that by your daily sessions before you agree to a unit price.
Then use the discounts OpenAI publishes:
- Batch API: GPT-4.1 models are available at an additional 50% discount for work that doesn't need an immediate response.
- Prompt caching: cached input on GPT-4.1 costs $0.50 versus $2.00 per million tokens.
- Smaller tiers: GPT-4.1 mini runs $0.40/$1.60 and nano $0.10/$0.40. Both are worth testing for classification and routing before you default to the full model.
Last, assume migrations will happen. OpenAI says affected customers will always be notified by email and in our documentation. So far, every cheaper option has arrived under a new name. This is a forecast, not an OpenAI commitment: if that pattern holds, the next price drop will also come as a new model you have to switch to, not a discount on the one you have deployed. Budget a sprint for that swap every year or so. On these numbers, it pays for itself.
Sources
- openai.com – "GPT-4 | OpenAI" (2023)
- openai.com – "Introducing GPT-4.1 in the API | OpenAI" (2025)
- openai.com – "New models and developer products announced at DevDay | OpenAI" (2024)
- developers.openai.com – "Deprecations | OpenAI API" (2026)
- developers.openai.com – "GPT-4 Turbo Model | OpenAI API"